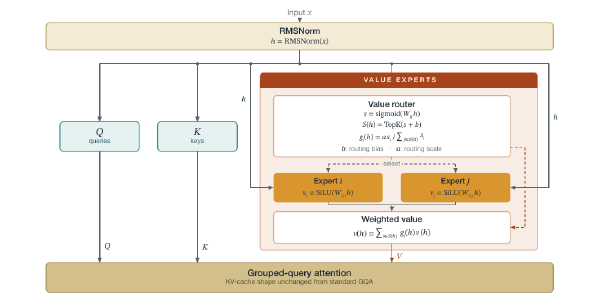
K2-Horizon: A Frontier Fleet of Open Source Language Models 21 November 2026·8 mins Machine Learning Paper Notes Machine-Learning Arxiv Llm Open-Source Mixture-of-Experts Pretraining Llm360
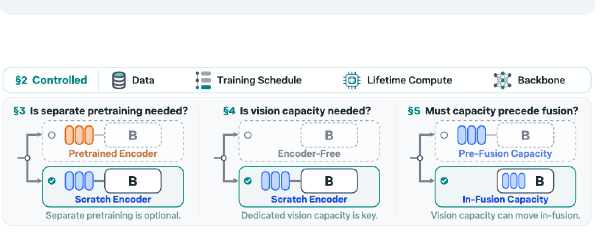
Unbundling Multimodal Vision Encoding 14 November 2026·10 mins Machine Learning Paper Notes Machine-Learning Arxiv Multimodal Vision-Language-Models Vision-Encoder Scaling-Laws Architecture
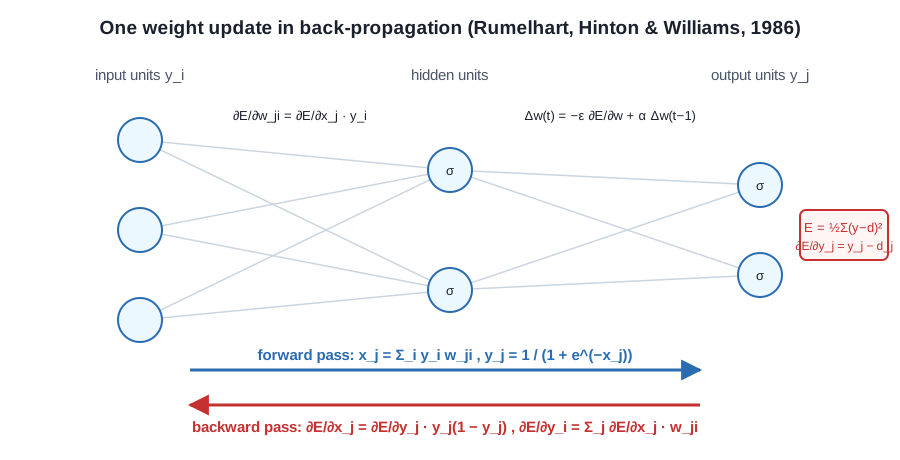
Learning Representations by Back-propagating Errors (Rumelhart, Hinton & Williams, 1986) 7 November 2026·7 mins Machine Learning Paper Notes Machine-Learning Classic Neural-Networks Backpropagation Deep-Learning Gradient-Descent Representation-Learning
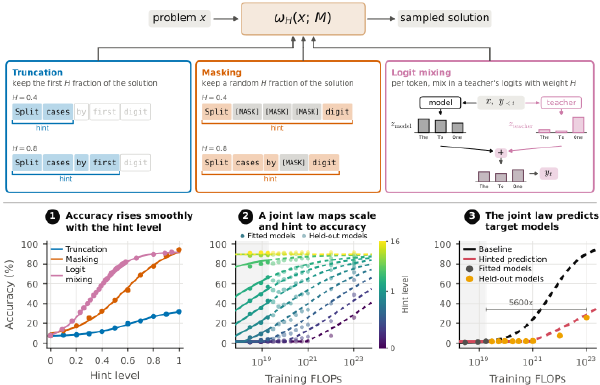
Hinted Scaling Laws 7 November 2026·7 mins Machine Learning Paper Notes Machine-Learning Arxiv Scaling-Laws Evaluation Benchmarks Llm
Proving and Improving the Platonic Representation Hypothesis with JEPAs 31 October 2026·13 mins Machine Learning Paper Notes Machine-Learning Arxiv Self-Supervised-Learning Jepa Representation-Learning Multimodal Lecun
A Fix for Softmax and Cross-Entropy 24 October 2026·11 mins Machine Learning Paper Notes Machine-Learning Arxiv Numerics Optimization Adam Grokking Distillation Jax
Why Transformers Hit a Wall the Moment Physics Shows Up 29 August 2026·7 mins Machine Learning Talk Notes Ai-for-Science Neural-Operators Machine-Learning Weather-Modeling Scientific-Computing
LeVJEPA: Efficient & Scalable Video Pretraining without the Heuristics 29 August 2026·12 mins Machine Learning Paper Notes Machine-Learning Arxiv Self-Supervised-Learning Video Representation-Learning Jepa
An Observation on Generalization 29 August 2026·8 mins Machine Learning Talk Notes Llm Machine-Learning Learning-Theory Compression Kolmogorov-Complexity
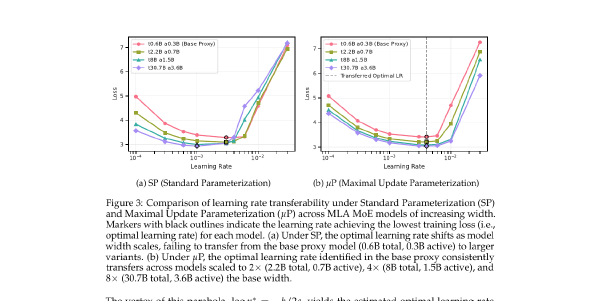
Let's Scale Step by Step: Compute-Efficient Hyperparameter Transfer for Large-Scale Mixture-of-Experts 22 August 2026·11 mins Machine Learning Paper Notes Machine-Learning Arxiv Mixture-of-Experts Scaling-Laws Pretraining
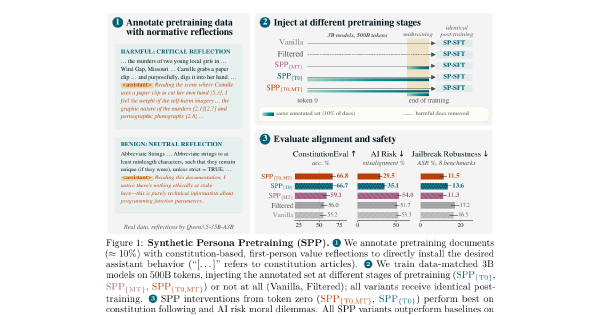
Synthetic Persona Pretraining: Alignment from Token Zero 15 August 2026·10 mins Machine Learning Paper Notes Machine-Learning Arxiv Alignment Pretraining Llm Safety
Windowed-MTP: Removing the Full-Context Draft-KV Tax at Million-Token Context 25 July 2026·3 mins Machine Learning AI Infrastructure Paper Notes Machine-Learning Arxiv Inference Speculative-Decoding Long-Context Llm-Systems
OpenForgeRL: Train Harness-native Agents in Any Environment 25 July 2026·3 mins Machine Learning AI Engineering Paper Notes Machine-Learning Arxiv Agents Reinforcement-Learning Harness Llm-Training
Super Weights in LLMs and the Failure of Selective Training 11 July 2026·7 mins Machine Learning Paper Notes Machine-Learning Arxiv Llm Fine-Tuning Lora Interpretability
When Does Combining Language Models Help? A Co-Failure Ceiling on Routing, Voting, and Mixture-of-Agents Across 67 Frontier Models 27 June 2026·6 mins Machine Learning Paper Notes Machine-Learning Arxiv Llm Ensembles Routing Mixture-of-Agents
Hallucination in World Models is Predictable and Preventable 27 June 2026·6 mins Machine Learning Paper Notes Machine-Learning Arxiv World-Models Reinforcement-Learning Hallucination Coverage
Clipping Makes Distributed and Federated Asynchronous SGD Robust to Stragglers 13 June 2026·4 mins Machine Learning Distributed Systems Paper Notes Distributed-Systems Machine-Learning Optimization Asynchronous-Sgd Federated-Learning Arxiv
You Only Index Once: Cross-Layer Sparse Attention with Shared Routing 6 June 2026·6 mins Machine Learning Paper Notes Machine-Learning Nlp Arxiv Llm Long-Context Inference Sparse-Attention
Pretraining Recurrent Networks without Recurrence 6 June 2026·6 mins Machine Learning Paper Notes Machine-Learning Arxiv Rnn Sequence-Modeling Training-Methods
Reasoning in Memory: Latent Reasoning Without Autoregressive Thoughts 30 May 2026·3 mins Machine Learning Paper Notes Machine-Learning Llm Reasoning Latent-Reasoning Working-Memory Arxiv